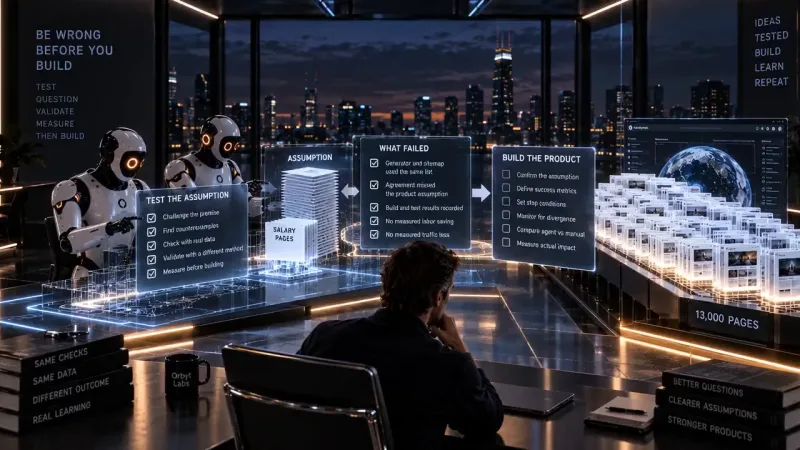
Be Wrong Before You Build.
I want agents to help test the assumption before I build. My salary page failure shows what the existing checks missed.
Key findings
- I have not measured whether agent assistance makes product validation cheaper.
- A pay ranking filled 110 of 150 role slots with executive titles; the passing checks shared the same selected list.
- I keep simulated reactions separate from observed responses and behavior.
- I write the rejection condition before the result and limit it to the decision the experiment can actually test.
Key measurements
| Measure | Value | Source and date |
|---|---|---|
| Role slots filled by the pay ranking in the documented incident | 110 of 150 | Aug 5, 2026 · Justin Bartak, AI Builds AI. I Found the Ceiling. (August 2026) |
I want to find the bad assumption before I build around it. I have a documented case of missing that check. I do not yet have a comparison showing that agents make product validation cheaper.
Shorten the path. Keep the uncertainty visible.
I need a test that can reject the product assumption before I expand the build.
At Orbyt Labs, I have zero paying customers. Jobs, Intelligence, and Orbyt One are early access waitlists. The case below concerns my own salary pages.
Which assumption did I build around?
The failure is entry 37 in the public failure corpus, dated August 5, 2026. My published account of the selection failure also records how the page generator and sitemap agreed while missing roles named in queries.
The incident records a budget of 150 roles, each with 50 city pages. Forty AI roles were curated. The remaining 110 slots were filled by sorting the catalog by its stored median pay baseline. All 110 went to executive titles.
My US salary figures are computed estimates. I scale a national role baseline by a regional cost of living index. That baseline does not measure searches. I had let pay decide. Its ranking determined which pages existed. I had not established that it selected the roles people were looking for.
The comment above the curated list said seniority variants were deliberately excluded. The next function put them back. I had missed the contradiction between the exclusion comment and the filler.
The generated pages and sitemap imported the same selected list. Their agreement established that they used that list consistently. None of the repository checks described in the incident compared the selected roles with recorded search queries.
A passing build did not answer the product question.
What did the test look like?
The incident was found while answering a Bing question. Bing Webmaster query data supplied an outside comparison. The record names software engineer in San Francisco, registered nurse in New York, dentist in Phoenix, and accountant in Dallas as missing combinations.
These were URL checks prompted by recorded queries. A checked URL returning 404 does not establish that a searcher visited it. I cannot turn those checks into a count of failed visits.
The available record does not preserve the query window, the complete query extract, the tested URL list, or the selection procedure. I cannot make the aggregate query counts reproducible from that record. I am leaving them out.
The repair put an explicit list of occupations with broad employment and roles named in query data ahead of the filler. It excluded seniority variants from automatic filling while allowing deliberate exceptions in the curated lists. The page budget stayed unchanged.
Entry 37 records a successful build. The software engineer page for San Francisco and seven other checked combinations were present on disk. Every city directory for the vice president of partner engineering role was gone.
The incident also records six guard tests. Reintroducing the original ranking made three fail. The correction was restored. The tests returned to green. Negative cases checked that the filter left software engineer, registered nurse, CEO, CTO, and general counsel alone.
I can point to the recorded repair and its checks. They establish selection behavior and built artifacts. They do not establish how many people wanted those pages or whether anyone used them.
What does the record carry?
The public corpus is an index. It gives entry 37 a date, classification, title, and countermeasure path. It does not contain the raw search observations. I would need those observations to publish a reproducible query comparison.
The incident says the rule survived eight weeks before detection. I have no measured repair duration. Nor do I have a record establishing when the relevant queries first became available. I cannot turn elapsed time into labor saved or wasted.
The records identify gaps in coverage. They cannot quantify lost impressions, visits, or revenue. They also do not establish that the executive pages attracted no searches. I have no measured result for what would have happened with different pages.
The decision ledger shows how I can preserve a correction. D-0014 explicitly supersedes D-0004. Both remain listed. For a product test, I would retain the rejected assumption and record which build task changed.
Which uncertainty would I test first?
Suppose I get three requests for an invoice dashboard from prospective users. I have not run this test. I would first ask which decision the dashboard should help each person make.
For this hypothetical, the decision would be whether to send overdue invoice reminders during the next scheduled weekly bookkeeping review. I would record each participant's planned action before showing a plain message with the overdue count.
Before that review ends, I would confirm that each person received the message, could explain the count, and had a real reminder decision to make. I would then record any change in their chosen action.
My rejection condition would be narrow. If everyone meeting those conditions keeps the same decision, I would not approve a dashboard based on this message test. A missed message or absent decision would leave the test inconclusive.
Even a completed test without a changed decision would leave open whether a screen adds value through timing, history, or detail. If a participant acted on the message, I would still need to check whether the information helped them make a better decision.
What would I ask an agent to check?
For a future salary coverage check, I would ask an agent to compare a dated query export with the proposed role list. Its output would pair each original query with the mapped role, intended URL, check time, and response status.
I would review ambiguous mappings before changing the list. Several phrasings could refer to one role. An unmapped query would stay visible. A request that could not be completed would remain unobserved rather than become evidence of a missing page.
For the dashboard hypothetical, I would ask an agent to identify which source fields determine overdue status and flag missing payment updates. I would check that I could reconstruct the count before showing it to a participant.
To test the cost claim, I would compare work with and without an agent on the same frozen input. I would record elapsed time, my review and correction time, mapping errors, and agent usage. I have not run that comparison.
I would keep the source export and mappings beside the report. Several summaries could use one export. That would still be one source. I need to inspect how the agent reached its conclusion before deciding what to build.
Which customer evidence is real?
I would use a simulated skeptical buyer to draft questions or challenge wording. I would label that output as preparation. It would contain no observed response from a prospective user.
Useful preparation. Still synthetic.
I cannot use an agent's simulated customer to validate an idea another agent proposed. That would put my own assumptions on both sides of the test. Realistic dialogue does not supply an interview that never happened.
The salary case gives me a concrete reason to insist on that distinction. The generator and sitemap shared a selection rule. Asking another agent to summarize that agreement would not supply the missing comparison with search queries.
Can the experiment change my mind?
I would write the rejection condition first.
If the test supports the idea, I attach the result to the build task. If it contradicts the idea, I close or rewrite the task. If it is inconclusive, I record the unanswered question.
At Orbyt Labs, the Collective's recurring agent seats produce committed reports, proposals, and repairs. I keep authority over every gate a merge to main must pass, every dollar, every customer-facing change, and any widening of agent authority.
The Collective runs only at Orbyt Labs. It is not for sale. It has never been run elsewhere. Its reports can inform my next product decision. Responsibility for that decision stays with me.
A prototype still leaves reliability, access control, support, and operating cost to check. A finding about usefulness answers one question. I would keep the remaining checks on the task instead of treating the experiment as permission to release.
What would I do next?
I would choose one feature justified by an untested assumption. Before requesting a prototype, I would name the decision, the observation that could change it, and the records I would need to inspect afterward.
For salary coverage, that means comparing the proposed pages with a dated query extract and reviewing the mappings. For the dashboard, it means observing a specific decision during a scheduled review. Neither test starts with a mockup.
The salary rule survived eight weeks. The correction changed the selection list and required a rebuild. I do not know its labor cost or effect on demand. I know which assumption the passing checks left untested.
Related reading:
- You Ship What You Tolerate. how the work I accept becomes the standard
- Verification Is the New Literacy questions for deciding what a check actually proves
- Your Next Customer Is an Agent. product questions raised by agents comparing what they can read
- Leadership Is the New Bottleneck why deciding what to build remains my responsibility
Methodology
I checked numbered incident 37 in docs/lessons-learned.md, its public Failure Corpus index entry, the published self-improvement account, the Decision Ledger, and the Collective operating reference in the repository on September 10, 2026. The detailed build and guard figures come from the incident narrative. The public corpus indexes the incident but does not expose its raw query evidence. I ran no product experiment or cost comparison for this article.
Limitations
This is one documented incident at Orbyt Labs. The available records omit the raw query extract, query window, full tested URL list, and selection procedure, so I omit the aggregate query totals. URL checks do not establish failed visits. Elapsed time does not measure labor, and the records do not quantify lost traffic or revenue. The dashboard test and agent cost comparison are unrun hypotheticals. I reviewed recorded build results without rerunning the build or original URL checks.
Sources
- Orbyt Labs, Failure Corpus Retrieved Sep 10, 2026.
- Justin Bartak, AI Builds AI. I Found the Ceiling. (August 2026) Retrieved Sep 10, 2026.
- Orbyt Labs, Decision Ledger Retrieved Sep 10, 2026.
- Orbyt Labs, How the Collective works Retrieved Sep 10, 2026.
- Justin Bartak, You Ship What You Tolerate. Retrieved Sep 10, 2026.
- Justin Bartak, Verification Is the New Literacy Retrieved Sep 10, 2026.
- Justin Bartak, Your Next Customer Is an Agent. Retrieved Sep 10, 2026.
- Justin Bartak, Leadership Is the New Bottleneck Retrieved Sep 10, 2026.
AI product research questions? Answers.
Related research
- Governing an agent leadership team Sep 2026.
- I Ran 830 Agents in One Long Horizon Session. Jul 2026.
- My C-Suite of Agents Named Themselves. Jul 2026.
Follow the work.
I write these while the Machine runs. Get the next one wherever you already read.
- Subscribe on Substack (opens in a new tab)
- RSS feed
- Bluesky (opens in a new tab)
- Threads (opens in a new tab)
Add Orbyt Labs as a preferred source on Google (opens in a new tab)